This page: Fits the long- and short-form measurement CFAs for Study 5 and evaluates the preregistered external-validity and nomological-network hypotheses (directional Pearson tests, Fisher-z TOST for equivalence rows, quadratic fits for u-shape rows). No FIMI outcome was administered, so this page validates the predictor construct network rather than estimating FIMI prediction. It closes with an exploratory temporal-invariance ladder against the Lithuanian Study 2 wave.
Study 5 (Lithuania, Mar-Apr 2026) contributes the following cross-study evidence:
Stage 2/6: long- and brief-form CFAs validate the predictor-side measurement structure (no FIMI outcome by design).
Stage 3: measurement-only hybrid MIMIC (S5_long_mimic, exploratory) parallels the S2 / S3 hybrid parameterisation on a fresh Lithuanian sample one year on from Study 2 — without a downstream FIMI prediction layer, so flagged as exploratory and read alongside S5_long_cfa.
Stage 7: exploratory S2 ←→ S5 temporal invariance ladder against the Lithuanian Study 2 wave.
Stage 8: preregistered nomological-network grid (directional Pearson, Fisher-z TOST equivalence, quadratic u-shape) against CMQ, populism, ESS trust, RWA, ITT, feeling thermometers, and the I-PANAS-SF.
Study 5 is the external-validity and nomological-network wave for the DisInformeter scale. The questionnaire was fielded between March and April 2026 to undergraduates in Vilnius University’s VU SONA participant pool, who completed the full DisInformeter long-form battery plus a curated set of external anchor scales (CMQ, populist attitudes, ESS institutional trust, RWA, ITT, feeling thermometers, and the I-PANAS-SF). No news-headline (FIMI) items were administered: this wave deliberately isolates the predictor side of the model so it can be benchmarked against established constructs without making any criterion-prediction claim.
The analyses below mirror the order of the prereg deliverables:
Sample profile — who completed the survey and how reliable were the composite scores.
Measurement structure — long-form and brief CFAs for the DisInformeter predictors.
External validity and nomological-network tests — the preregistered hypothesis grid.
Secondary tests — u-shape ambivalence hypotheses and the omnibus PANAS discriminant.
Temporal stability — exploratory cross-time invariance against Study 2 (Lithuania, Mar 2025).
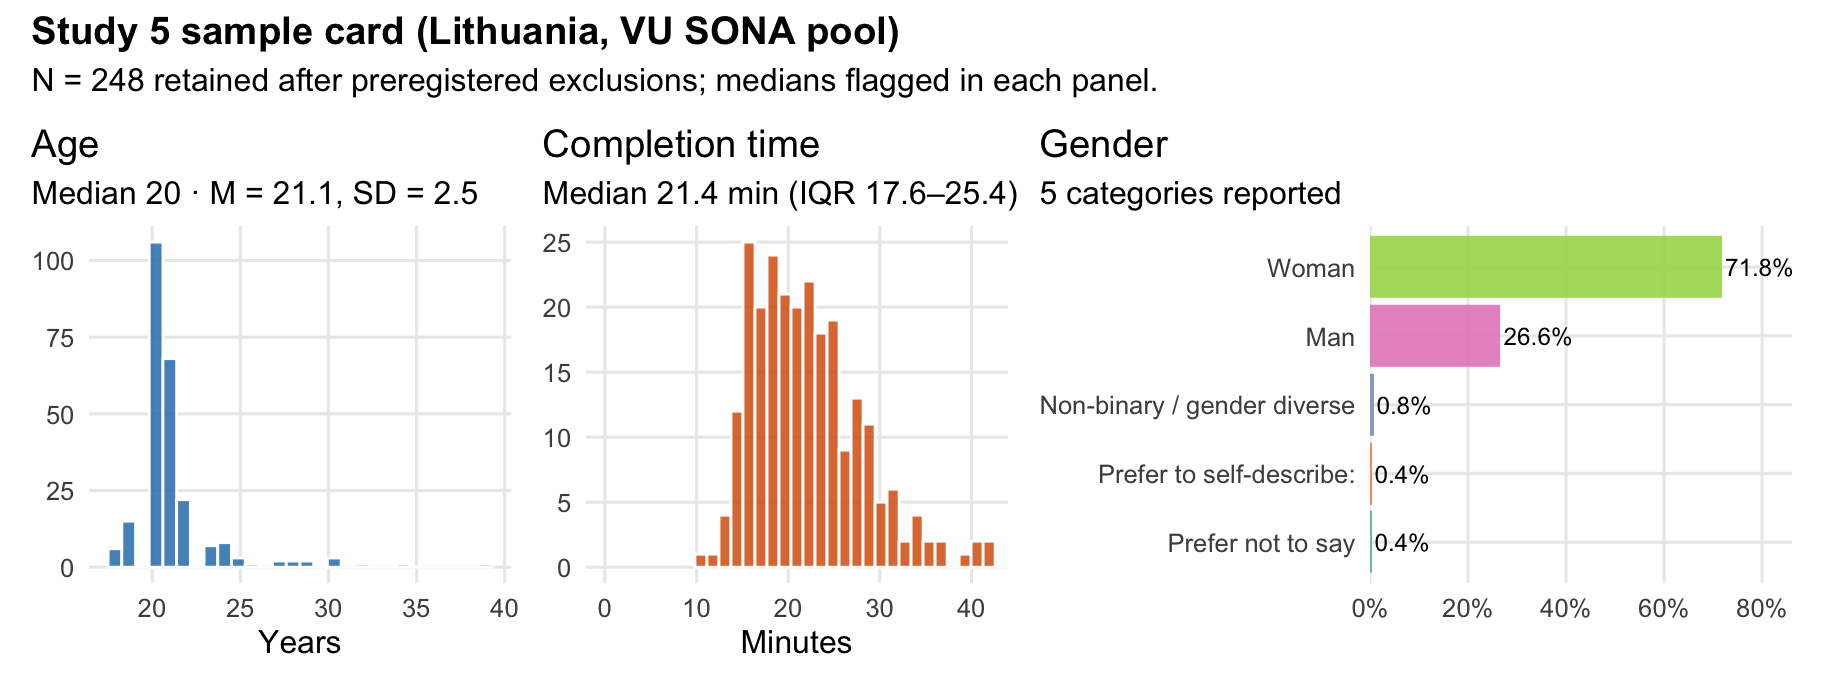
The retained Study 5 sample contains 248 respondents.
Within the eight-stage pipeline, Study 5 contributes to Stage 2 first-order measurement validation, Stage 6 scale-reduction/deployment adaptation through the brief CFA, Stage 7 exploratory temporal invariance against S2, and Stage 8 external validity and nomological-network validation. It does not contribute to Stage 5 FIMI prediction because FIMI was intentionally not fielded.
Sample profile
Most respondents (75.8%) are Lithuanian nationals; the second-largest group accounts for 13.3%. Self-reported English proficiency averages 7.7 on the 1–5 scale (SD = 1.0), indicating that the English-language items were well within reach for the panel.
Scale reliability
We compute Cronbach’s α and McDonald’s ω (where ≥ 3 indicators exist) for every entry in the Study 5 scale registry. For first-order constructs that are also reflectively identified in the cached S5_long_cfa measurement model we additionally report the average variance extracted (AVE) computed from the standardized loadings. External-anchor scales and higher-order block aggregates that are not modeled as CFA latents on this page get — in the AVE column.
Study 5 multi-item scale reliability (Cronbach's α; McDonald's ω where ≥ 3 indicators; AVE from `S5_long_cfa` standardized loadings for the 15 first-order CFA latents)
Scale
# items
α
ω
AVE
GEN
8
0.57
0.66
—
THREAT
12
0.85
0.85
0.32
THREAT_GAY
3
0.97
0.97
—
THREAT_MIGR
2
0.90
—
—
THREAT_FT
3
0.71
0.75
—
CET
8
0.79
0.79
0.44
EXPL
5
0.78
0.78
0.44
GAY
6
0.91
0.92
0.82
MIGR
7
0.90
0.90
0.77
ABAND
8
0.87
0.87
0.36
UNP
4
0.87
0.87
—
ABAN_STATE
5
0.92
0.92
—
CEN
6
0.94
0.94
—
FEAR
6
0.83
0.84
0.53
PRAGR
6
0.86
0.87
0.58
PRAGCH
6
0.87
0.87
0.53
SUP_GEN
8
0.92
0.93
—
SUPR
12
0.92
0.93
0.55
SUPCH
11
0.91
0.91
0.55
CMQ
5
0.84
0.84
—
POP
9
0.40
0.46
—
POP_PEOPLE
3
0.36
0.49
—
POP_ELITE
3
0.27
0.48
—
POP_MANI
3
0.18
0.43
—
TRUST_LOCAL
5
0.86
0.86
—
RWA
6
0.56
0.59
—
ITT_IMI
6
0.94
0.94
—
ITT_IMI_SYM
3
0.96
0.97
—
ITT_IMI_REAL
3
0.93
0.93
—
ITT_LGBT
8
0.93
0.93
—
ITT_LGBT_SYM
4
0.94
0.95
—
ITT_LGBT_REAL
4
0.82
0.84
—
PANAS_PA
5
0.73
0.74
—
PANAS_NA
5
0.81
0.82
—
Measurement model: long form
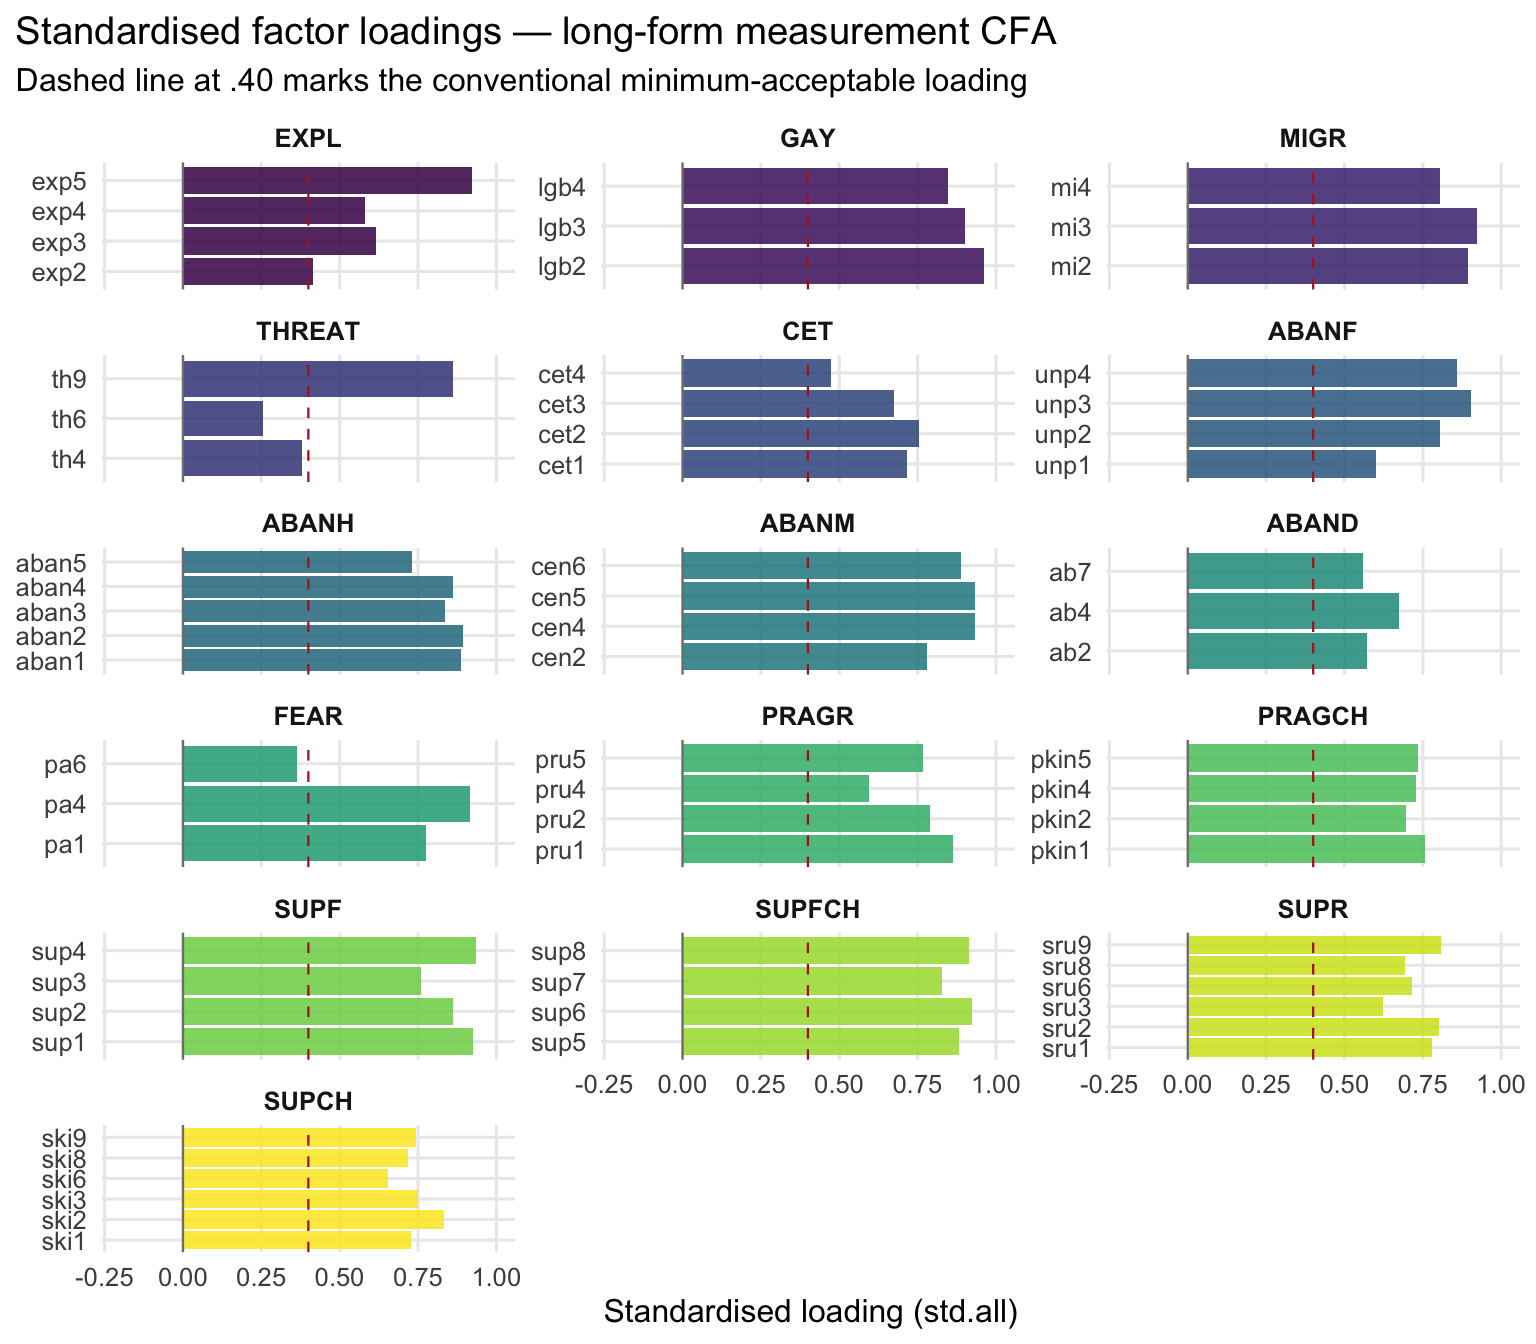
NoteS5_long_cfa — S5 long-form measurement CFA
Study: S5 · Family: Measurement
Pure measurement model for the Study 5 validation wave (n = 248 Lithuanian VU SONA pool). Sixteen reflective predictor latents reuse the S2/S3 indicator vocabulary and add CET, SUPF (Russia affective admiration, sup1–sup4 — identical content to S2/S3 SUPF), SUPFCH (China affective admiration, sup5–sup8, newly modelled in this wave), and SUPCH (China beliefs, ski*) for the constructs newly available in Study 5. No FIMI factor (S5 deliberately omits the news-headline battery). All latents are free to covary; structural paths are tested elsewhere via factor-score correlations against the validation anchors.
Measurement-only specification (no structural regressions).
S5 fields both the first-order parent blocks used in S2 / S3 (EXPL, GAY, MIGR; ABANF, ABANH, ABANM; PRAGR; S5 legacy: UNP, ABAN_STATE, CEN) and the direct affective indicators (th9/th4/th6, ab2/ab4/ab7, pa1/pa4/pa6), so the hybrid MIMIC representation is locally available. The catalogued sibling S5_long_mimic exercises it as a measurement-only model — S5 has no FIMI battery, so there is no downstream prediction layer to close the structural side of identification. The composites are identified jointly by their three reflective direct indicators and their ~ regressions on first-order parents; the canonical S5 S5_long_mimic spec now also includes a SUPFCH direct-affect composite (the China-admiration counterpart to SUPF, the general foreign-admiration block; S5 legacy: SUP_GEN), so the foreign-power admiration block is no longer asymmetric.
NoteS5_long_mimic — S5 hybrid MIMIC measurement-only model (exploratory)
Study: S5 · Family: Higher-order (hybrid MIMIC)
Hybrid MIMIC sibling of S5_long_cfa, fitted as a measurement-only model because S5 fields no FIMI battery. The S2 / S3 composites (THREAT, ABAND, FEAR) are reflectively identified by their direct affective indicators (th9 + th4 + th6, ab2 + ab4 + ab7, pa1 + pa4 + pa6) and simultaneously regressed on their S5 first-order parents (THREAT on EXPL/GAY/MIGR; ABAND on ABANF/ABANH/ABANM; FEAR on PRAGR). The remaining S5 first-order constructs (CET, PRAGCH, SUPF, SUPFCH, SUPR, SUPCH) appear as reflective latents only — S5 does not field a higher-order composite indicator for foreign-power admiration, so SUPR and SUPCH do not get a MIMIC layer. Exploratory: the model converges in ~9 s under MLR / FIML but the vcov is borderline non-positive-definite (smallest eigenvalue ≈ -2.5e-14, numerically zero) and lavaan flags a single negative observed-variable residual variance, consistent with S5’s lack of a downstream prediction layer to absorb the composites’ residual variance (the S2 / S3 hybrids rely on FIMI ~ THREAT + ABAND + FEAR + SUPF to close the structural side of identification). Catalogued so the cross-wave temporal-invariance ladder (S2 ←→ S5) can probe the hybrid MIMIC parameterisation as well as the reflective measurement model, with the caveat that S5’s measurement-only fit is not a substitute for the joint measurement-plus-prediction estimation available on S2 / S3.
Study 5 hybrid MIMIC (measurement-only) — global fit
Model
CFI
TLI
RMSEA
SRMR
χ²
df
p
S5_long_mimic
0.819
0.805
0.070 [0.067, 0.073]
0.086
4 150.5
1864
<0.001
The hybrid MIMIC reading is exploratory on this wave: the optimizer converges in under 10 s but lavaan flags a borderline non-positive-definite vcov (smallest eigenvalue ≈ -2.5e-14, numerically zero) and a single negative observed-variable residual variance, consistent with S5’s lack of a downstream FIMI prediction layer to absorb the composites’ residual variance. The fit is therefore read alongside S5_long_cfa (which is the canonical S5 measurement model) rather than as a substitute for it. Its main use is feeding the cross-wave S2 ←→ S5 temporal-invariance ladder where the same hybrid MIMIC parameterisation can be tested under both Lithuanian samples.
Measurement model: brief form
NoteS5_brief_cfa — S5 brief measurement CFA
Study: S5 · Family: Abbreviated
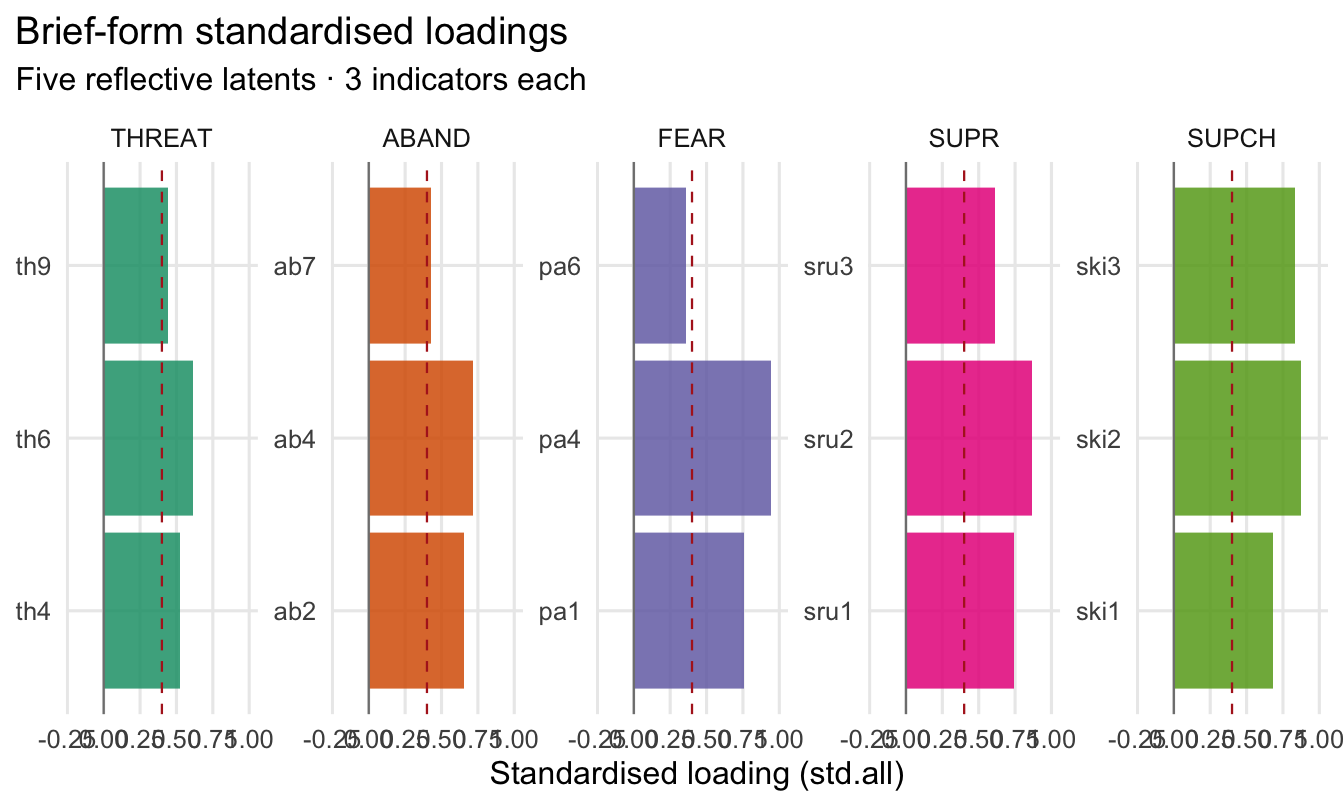
Three-indicator-per-construct reduced deployment form parallel to S2_brief / S3_brief. Because S5 has no FIMI battery, this entry is a pure five-factor measurement model: THREAT, ABAND, FEAR, SUPR, SUPCH. Used to confirm that the brief scale’s measurement structure survives in a fresh Lithuanian validation sample one year on from Study 2.
Measurement-only specification (no structural regressions).
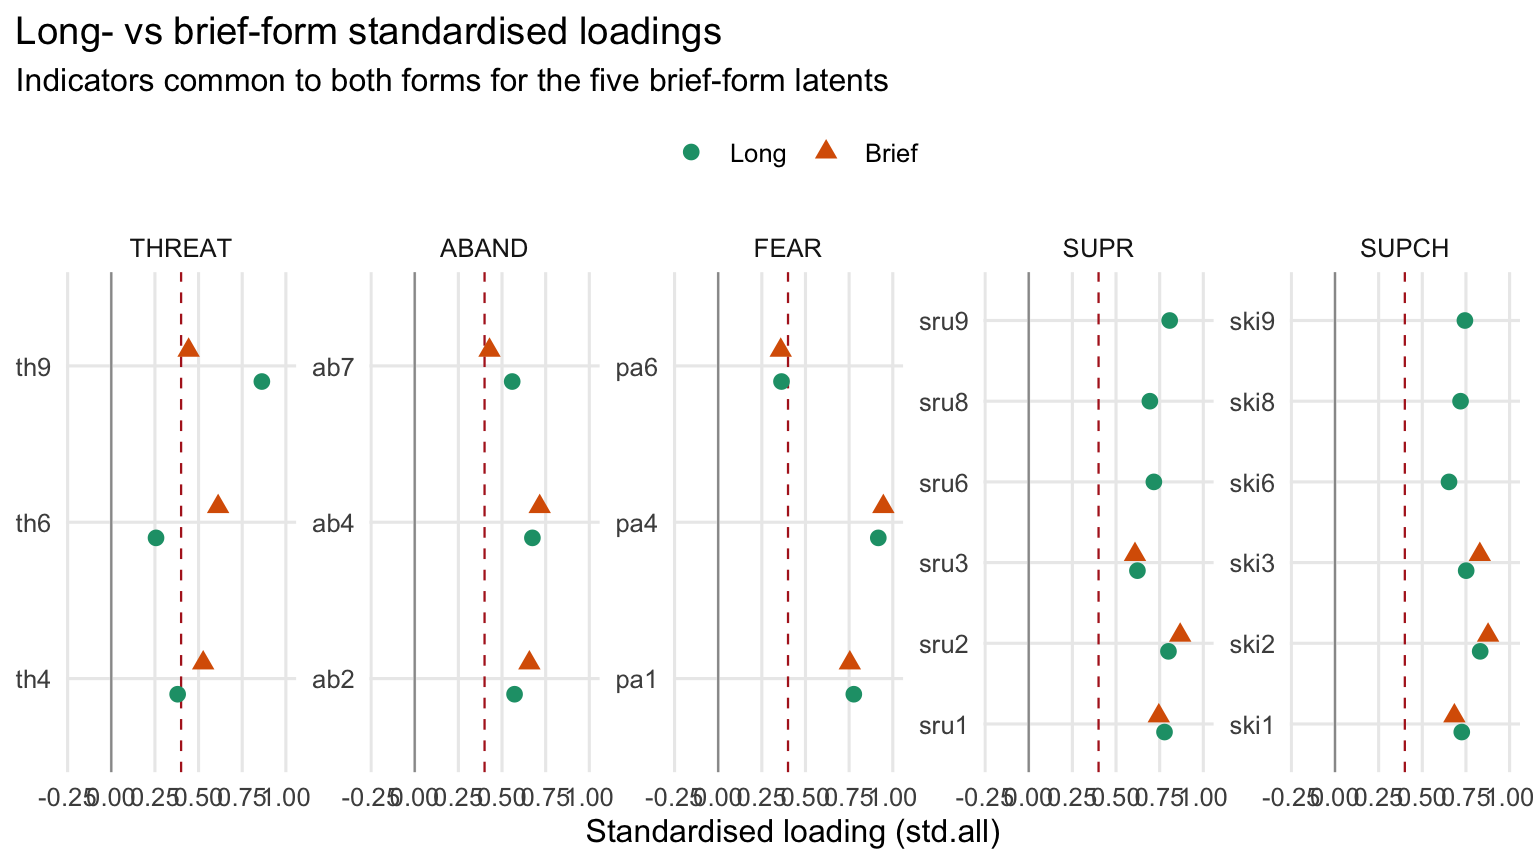
We directly compare the brief-form CFA against the long-form CFA on the five constructs that survive scale reduction (THREAT, ABAND, FEAR, SUPR, SUPCH). Two diagnostics are reported: (i) a loadings overlay so the per-indicator standardized loadings can be inspected side-by-side, and (ii) a Pearson correlation between the long- and brief-form factor scores for each shared construct. A correlation near 1.0 indicates the brief form recovers the same latent location as the long form for that construct. Cross-study synthesis of the brief-vs-long path equivalence — including against S2 and S3 — is on 4d Deployment and invariance.
Study 5 long- vs brief-form factor-score correlations (Pearson r per construct)
Construct
Pearson r (long vs brief)
n
THREAT
0.601
248
ABAND
0.841
248
FEAR
0.996
248
SUPR
0.922
248
SUPCH
0.938
248
Takeaway. Factor-score correlations range from 0.60 to 1.00 (median 0.92) — the brief form approximates the long-form factor locations only partially; at least one construct falls below r = .80 and should be inspected before deployment.
External validity and nomological network
The preregistered hypothesis grid is loaded directly from validation_hypotheses_prereg.csv. Each preregistered row is resolved into a Pearson correlation; one-sided p-values are used for directional + / − rows, Fisher-z TOST against ±.30 for <|.30| equivalence rows, and a quadratic fit on centred predictors for u-shape rows. Cells flagged N/A in the prereg are not tested — they document that we did not predict a relationship and deliberately did not preregister an analysis (they would not be relevant to validating the DisInformeter). Spearman ρ is reported as a sensitivity column (relevant when one anchor is a 0–100 feeling thermometer with heavy tails). These tests are external-validity and nomological-network evidence; they are not FIMI-prediction models.
Headline verdict
Per-construct scorecard
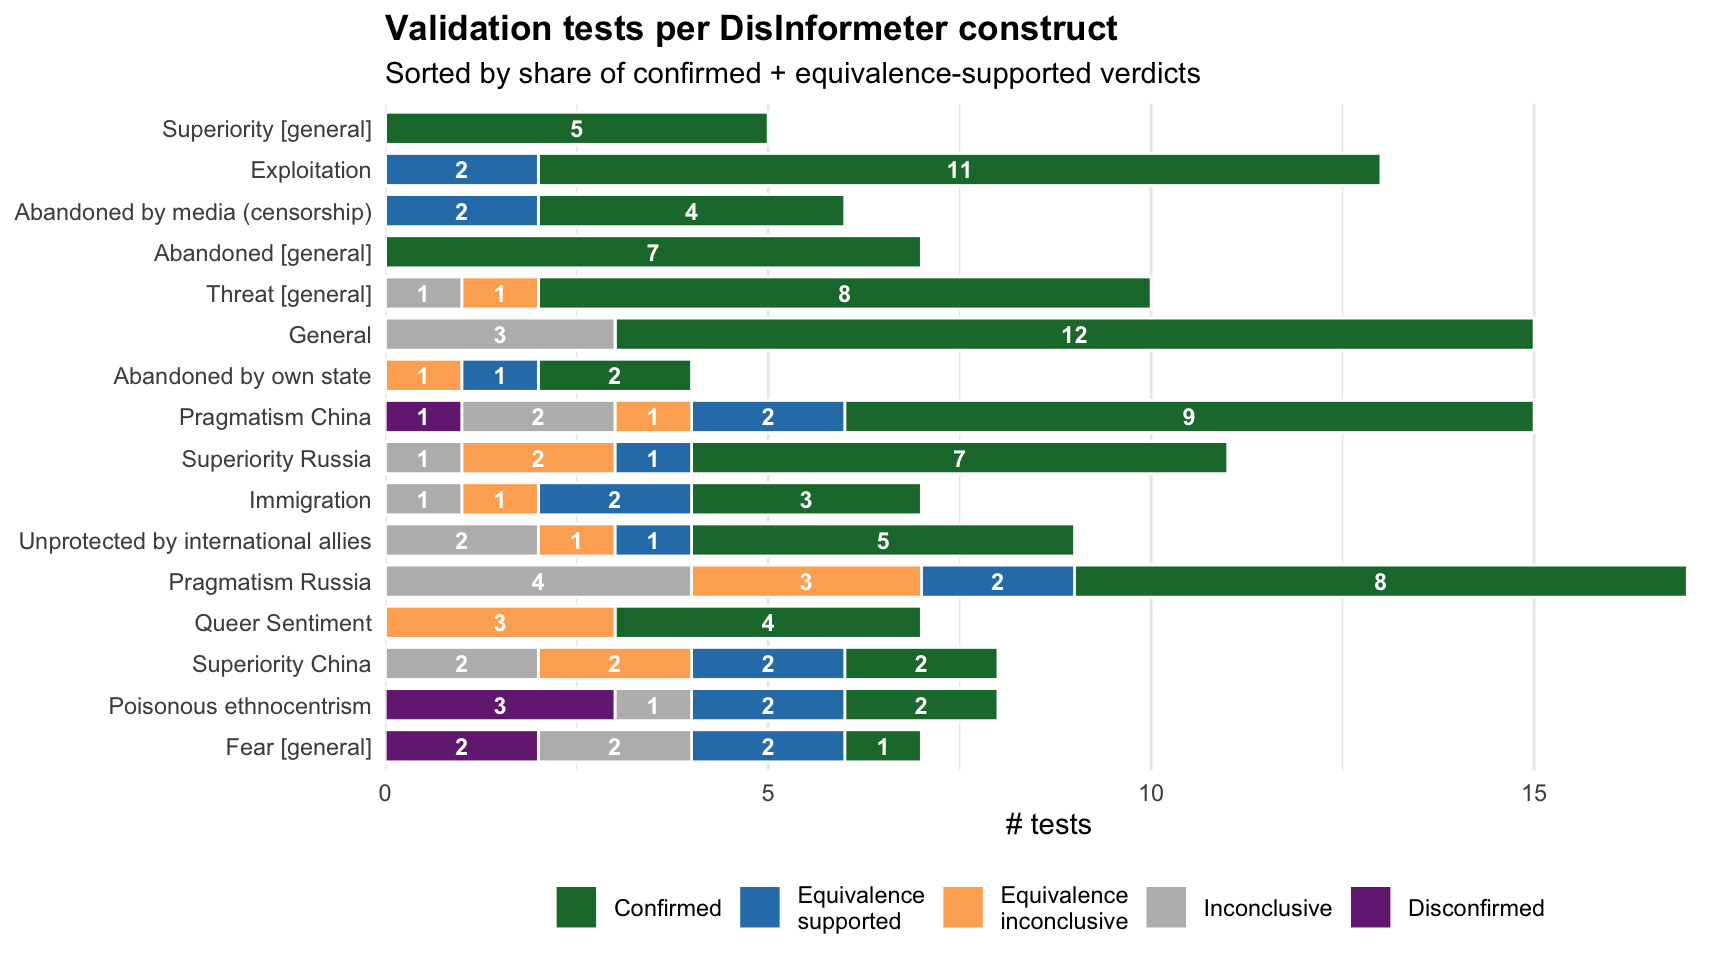
For each DisInformeter construct, the bar below partitions its preregistered tests by verdict. Constructs with the strongest convergent profile sit at the top; constructs where multiple predictions did not land sit at the bottom and are flagged for short-scale revision.
Correlation heatmap
The heatmap below is an interactive HTML widget. The default view shows every preregistered construct × validation-scale pair, colored by Pearson r. The View dropdown in the top-left corner switches between eight curated lenses on the data:
Preregistered validation tests only(default) — Pearson r for every preregistered pair.
All correlations (full grid) — every pairwise Pearson r between every DisInformeter construct scale and every validation scale in the data, including pairs that were not part of the preregistration.
Verdict: Confirmed / Equivalence supported / Equivalence inconclusive / Inconclusive / Disconfirmed — the preregistered grid with the corresponding verdict’s cells outlined in the scorecard color.
All verdicts (combined) — the preregistered grid with every verdict outlined at once.
Hover any cell for the construct × scale pair and the observed r (plus the verdict label when applicable).
Highlights & misses
The compact table below surfaces (a) the strongest convergent signature per construct — the single largest absolute Pearson correlation among confirmed tests — and (b) every preregistered prediction that came back disconfirmed. Everything else (full grid, all secondary rows, equivalence rows) is collected in the collapsible block underneath.
Headline convergent results and predictions that did not land
Construct
Target
Predicted
r
90% CI
n
Verdict
Strongest convergent signature
Abandoned [general]
scale_trust_local · items: ab3, ab5
−
-0.42***
[-0.52, -0.31]
248
Confirmed
Abandoned by media (censorship)
scale_cmq
+
0.45***
[0.35, 0.55]
248
Confirmed
Abandoned by own state
scale_trust_local
−
-0.41***
[-0.51, -0.30]
248
Confirmed
Exploitation
scale_rwa
+
0.49***
[0.39, 0.58]
248
Confirmed
Fear [general]
scale_panas_na
+
0.26***
[0.14, 0.37]
247
Confirmed
General
scale_feel_ru · items: gen5
+
0.61***
[0.53, 0.69]
247
Confirmed
Immigration
scale_itt_imi
+
0.75***
[0.69, 0.80]
248
Confirmed
Poisonous ethnocentrism
scale_rwa
+
0.40***
[0.29, 0.50]
248
Confirmed
Pragmatism China
scale_feel_ch
+
0.48***
[0.38, 0.57]
247
Confirmed
Pragmatism Russia
scale_feel_ru
+
0.56***
[0.47, 0.64]
247
Confirmed
Queer Sentiment
scale_itt_lgbt
+
0.90***
[0.87, 0.92]
248
Confirmed
Superiority China
scale_feel_ch
+
0.62***
[0.53, 0.69]
247
Confirmed
Superiority Russia
scale_feel_ru
+
0.64***
[0.56, 0.71]
247
Confirmed
Superiority [general]
scale_feel_ru
+
0.62***
[0.53, 0.69]
247
Confirmed
Threat [general]
scale_itt_lgbt · items: th9, th10, th11
+
0.85***
[0.81, 0.88]
248
Confirmed
Unprotected by international allies
scale_feel_eu
−
-0.37***
[-0.48, -0.26]
248
Confirmed
Prediction not met
Fear [general]
scale_feel_ru
∪
0.12
[0.00, 0.24]
247
Disconfirmed
Fear [general]
scale_feel_ch
∪
0.01
[-0.12, 0.13]
247
Disconfirmed
Poisonous ethnocentrism
scale_trust_eu
+
-0.14
[-0.26, -0.02]
248
Disconfirmed
Poisonous ethnocentrism
scale_trust_un
+
-0.09
[-0.21, 0.03]
248
Disconfirmed
Poisonous ethnocentrism
scale_trust_local
+
-0.03
[-0.15, 0.10]
248
Disconfirmed
Pragmatism China
scale_feel_ch · secondary: u-shape
∪
0.48***
[0.38, 0.57]
247
Disconfirmed
NoteFull preregistered hypothesis grid — every primary and secondary test
The table below contains every row run by run_validation_tests() (one row per hypothesis × target × item-subset cell). It is searchable, scrollable, and colour-coded by verdict — collapsed by default to keep the section above scannable.
Study 5 - full preregistered external-validity grid
Construct
Target
Predicted
r
90% CI
n
Verdict
Abandoned [general]
scale_trust_local
−
-0.42***
[-0.52, -0.31]
248
Confirmed
Abandoned [general]
scale_trust_local · items: ab3, ab5
−
-0.42***
[-0.52, -0.31]
248
Confirmed
Abandoned [general]
scale_pop
+
0.31***
[0.19, 0.42]
248
Confirmed
Abandoned [general]
scale_pop · items: ab3, ab5
+
0.29***
[0.17, 0.40]
248
Confirmed
Abandoned [general]
scale_panas_na
+
0.11*
[-0.01, 0.24]
247
Confirmed
Abandoned [general]
scale_feel_eu
−
-0.31***
[-0.42, -0.19]
248
Confirmed
Abandoned [general]
scale_feel_nato
−
-0.35***
[-0.46, -0.24]
248
Confirmed
Abandoned by media (censorship)
scale_cmq
+
0.45***
[0.35, 0.55]
248
Confirmed
Abandoned by media (censorship)
scale_trust_local
−
-0.40***
[-0.50, -0.28]
248
Confirmed
Abandoned by media (censorship)
scale_pop_elite
+
0.27***
[0.15, 0.38]
248
Confirmed
Abandoned by media (censorship)
scale_pop_elite · items: cen2
+
0.21***
[0.09, 0.33]
248
Confirmed
Abandoned by own state
scale_trust_local
−
-0.41***
[-0.51, -0.30]
248
Confirmed
Abandoned by own state
scale_pop_people
+
0.12*
[-0.01, 0.24]
248
Confirmed
Exploitation
scale_cmq
+
0.38***
[0.27, 0.48]
248
Confirmed
Exploitation
scale_trust_eu
−
-0.25***
[-0.36, -0.12]
248
Confirmed
Exploitation
scale_trust_un
−
-0.16**
[-0.28, -0.04]
248
Confirmed
Exploitation
scale_itt_imi
+
0.42***
[0.31, 0.52]
248
Confirmed
Exploitation
scale_itt_imi · items: exp4
+
0.41***
[0.30, 0.51]
248
Confirmed
Exploitation
scale_itt_lgbt
+
0.43***
[0.32, 0.52]
248
Confirmed
Exploitation
scale_itt_lgbt · items: exp3
+
0.29***
[0.17, 0.40]
248
Confirmed
Exploitation
scale_pop_elite
+
0.22***
[0.10, 0.33]
248
Confirmed
Exploitation
scale_rwa
+
0.49***
[0.39, 0.58]
248
Confirmed
Exploitation
scale_feel_eu
−
-0.38***
[-0.48, -0.26]
248
Confirmed
Exploitation
scale_feel_nato
−
-0.30***
[-0.41, -0.19]
248
Confirmed
Fear [general]
scale_trust_local
−
-0.07
[-0.20, 0.05]
248
Inconclusive
Fear [general]
scale_itt_imi
0 (|r|<.30>
0.09
[-0.03, 0.21]
248
Equivalence supported
Fear [general]
scale_itt_lgbt
0 (|r|<.30>
0.12
[0.00, 0.24]
248
Equivalence supported
Fear [general]
scale_pop_people
+
0.10
[-0.02, 0.23]
248
Inconclusive
Fear [general]
scale_panas_na
+
0.26***
[0.14, 0.37]
247
Confirmed
Fear [general]
scale_feel_ch
∪
0.01
[-0.12, 0.13]
247
Disconfirmed
Fear [general]
scale_feel_ru
∪
0.12
[0.00, 0.24]
247
Disconfirmed
General
scale_trust_eu
−
-0.11*
[-0.23, 0.02]
248
Confirmed
General
scale_trust_eu · items: gen2
−
-0.11*
[-0.23, 0.01]
248
Confirmed
General
scale_trust_local
−
-0.18**
[-0.30, -0.06]
248
Confirmed
General
scale_trust_local · items: gen1
−
-0.16**
[-0.28, -0.04]
248
Confirmed
General
scale_trust_un
−
-0.04
[-0.16, 0.09]
248
Inconclusive
General
scale_trust_un · items: gen2
−
-0.13*
[-0.25, 0.00]
248
Confirmed
General
scale_panas_na
+
0.10
[-0.03, 0.22]
247
Inconclusive
General
scale_feel_ch
+
0.44***
[0.33, 0.54]
247
Confirmed
General
scale_feel_ch · items: gen6
+
0.34***
[0.22, 0.44]
247
Confirmed
General
scale_feel_eu
−
-0.13*
[-0.25, 0.00]
248
Confirmed
General
scale_feel_eu · items: gen2
−
-0.03
[-0.15, 0.10]
248
Inconclusive
General
scale_feel_nato
−
-0.17**
[-0.29, -0.04]
248
Confirmed
General
scale_feel_nato · items: gen2
−
-0.12*
[-0.24, 0.00]
248
Confirmed
General
scale_feel_ru
+
0.34***
[0.22, 0.44]
247
Confirmed
General
scale_feel_ru · items: gen5
+
0.61***
[0.53, 0.69]
247
Confirmed
Immigration
scale_trust_eu
−
-0.16**
[-0.28, -0.04]
248
Confirmed
Immigration
scale_trust_un
−
-0.07
[-0.20, 0.05]
248
Inconclusive
Immigration
scale_itt_imi
+
0.75***
[0.69, 0.80]
248
Confirmed
Immigration
scale_itt_lgbt
0 (|r|<.30>
0.43***
[0.32, 0.53]
248
Equivalence inconclusive
Immigration
scale_rwa
+
0.29***
[0.17, 0.40]
248
Confirmed
Poisonous ethnocentrism
scale_trust_eu
+
-0.14
[-0.26, -0.02]
248
Disconfirmed
Poisonous ethnocentrism
scale_trust_local
+
-0.03
[-0.15, 0.10]
248
Disconfirmed
Poisonous ethnocentrism
scale_trust_un
+
-0.09
[-0.21, 0.03]
248
Disconfirmed
Poisonous ethnocentrism
scale_rwa
+
0.40***
[0.29, 0.50]
248
Confirmed
Poisonous ethnocentrism
scale_feel_eu
−
-0.15**
[-0.27, -0.03]
248
Confirmed
Poisonous ethnocentrism
scale_feel_nato
−
-0.06
[-0.19, 0.06]
248
Inconclusive
Pragmatism China
scale_trust_eu
−
-0.20***
[-0.32, -0.08]
248
Confirmed
Pragmatism China
scale_trust_eu · items: pru4
−
-0.10
[-0.22, 0.03]
248
Inconclusive
Pragmatism China
scale_trust_local
−
-0.21***
[-0.33, -0.09]
248
Confirmed
Pragmatism China
scale_trust_un
−
-0.12*
[-0.24, 0.00]
248
Confirmed
Pragmatism China
scale_trust_un · items: pru4
−
-0.02
[-0.14, 0.10]
248
Inconclusive
Pragmatism China
scale_pop_people
+
0.12*
[-0.01, 0.24]
248
Confirmed
Pragmatism China
scale_feel_ch
+
0.48***
[0.38, 0.57]
247
Confirmed
Pragmatism China
scale_feel_ch · secondary: u-shape
∪
0.48***
[0.38, 0.57]
247
Disconfirmed
Pragmatism China
scale_feel_eu
−
-0.34***
[-0.45, -0.23]
248
Confirmed
Pragmatism China
scale_feel_eu · items: pru4
−
-0.11*
[-0.23, 0.01]
248
Confirmed
Pragmatism China
scale_feel_nato
−
-0.32***
[-0.42, -0.20]
248
Confirmed
Pragmatism China
scale_feel_nato · items: pru4
−
-0.13*
[-0.25, -0.01]
248
Confirmed
Pragmatism China
scale_feel_ru
0 (|r|<.30>
0.37***
[0.26, 0.47]
247
Equivalence inconclusive
Pragmatism Russia
scale_trust_eu
−
-0.18**
[-0.30, -0.06]
248
Confirmed
Pragmatism Russia
scale_trust_eu · items: pru4
−
-0.10
[-0.22, 0.03]
248
Inconclusive
Pragmatism Russia
scale_trust_local
−
-0.19**
[-0.30, -0.06]
248
Confirmed
Pragmatism Russia
scale_trust_un
−
-0.06
[-0.18, 0.07]
248
Inconclusive
Pragmatism Russia
scale_trust_un · items: pru4
−
-0.02
[-0.14, 0.10]
248
Inconclusive
Pragmatism Russia
scale_itt_imi
0 (|r|<.30>
0.18**
[0.05, 0.30]
248
Equivalence supported
Pragmatism Russia
scale_itt_lgbt
0 (|r|<.30>
0.58***
[0.49, 0.66]
248
Equivalence inconclusive
Pragmatism Russia
scale_pop_people
+
0.06
[-0.07, 0.18]
248
Inconclusive
Pragmatism Russia
scale_feel_ch
0 (|r|<.30>
0.41***
[0.30, 0.51]
247
Equivalence inconclusive
Pragmatism Russia
scale_feel_eu
−
-0.24***
[-0.35, -0.11]
248
Confirmed
Pragmatism Russia
scale_feel_eu · items: pru4
−
-0.11*
[-0.23, 0.01]
248
Confirmed
Pragmatism Russia
scale_feel_nato
−
-0.24***
[-0.36, -0.12]
248
Confirmed
Pragmatism Russia
scale_feel_nato · items: pru4
−
-0.13*
[-0.25, -0.01]
248
Confirmed
Pragmatism Russia
scale_feel_ru
+
0.56***
[0.47, 0.64]
247
Confirmed
Pragmatism Russia
scale_feel_ru · secondary: u-shape
∪
0.56***
[0.47, 0.64]
247
Confirmed
Queer Sentiment
scale_itt_imi
0 (|r|<.30>
0.46***
[0.36, 0.56]
248
Equivalence inconclusive
Queer Sentiment
scale_itt_lgbt
+
0.90***
[0.87, 0.92]
248
Confirmed
Queer Sentiment
scale_rwa
+
0.51***
[0.42, 0.60]
248
Confirmed
Queer Sentiment
scale_feel_ru
+
0.38***
[0.27, 0.48]
247
Confirmed
Queer Sentiment
scale_feel_ru · items: lgb4
+
0.42***
[0.31, 0.52]
247
Confirmed
Superiority China
scale_itt_imi
0 (|r|<.30>
0.12
[-0.01, 0.24]
248
Equivalence supported
Superiority China
scale_pop_people
+
0.07
[-0.06, 0.19]
248
Inconclusive
Superiority China
scale_pop_people · items: ski9, ski10
+
0.04
[-0.08, 0.17]
248
Inconclusive
Superiority China
scale_rwa
+
0.31***
[0.19, 0.41]
248
Confirmed
Superiority China
scale_feel_ch
+
0.62***
[0.53, 0.69]
247
Confirmed
Superiority China
scale_feel_ru
0 (|r|<.30>
0.39***
[0.27, 0.49]
247
Equivalence inconclusive
Superiority Russia
scale_cmq
+
0.32***
[0.20, 0.43]
248
Confirmed
Superiority Russia
scale_itt_lgbt_sym
+
0.49***
[0.39, 0.58]
248
Confirmed
Superiority Russia
scale_itt_lgbt_sym · items: sru8, sru9
+
0.46***
[0.36, 0.55]
248
Confirmed
Superiority Russia
scale_pop_people
+
0.05
[-0.07, 0.17]
248
Inconclusive
Superiority Russia
scale_rwa
+
0.45***
[0.34, 0.54]
248
Confirmed
Superiority Russia
scale_feel_ch
0 (|r|<.30>
0.54***
[0.44, 0.62]
247
Equivalence inconclusive
Superiority Russia
scale_feel_eu
−
-0.24***
[-0.36, -0.12]
248
Confirmed
Superiority Russia
scale_feel_eu · items: sru7
−
-0.13*
[-0.25, 0.00]
248
Confirmed
Superiority Russia
scale_feel_ru
+
0.64***
[0.56, 0.71]
247
Confirmed
Superiority [general]
scale_rwa
+
0.31***
[0.20, 0.42]
248
Confirmed
Superiority [general]
scale_panas_pa
+
0.19**
[0.07, 0.31]
248
Confirmed
Superiority [general]
scale_feel_eu
−
-0.28***
[-0.39, -0.16]
248
Confirmed
Superiority [general]
scale_feel_nato
−
-0.30***
[-0.41, -0.18]
248
Confirmed
Superiority [general]
scale_feel_ru
+
0.62***
[0.53, 0.69]
247
Confirmed
Threat [general]
scale_cmq
0 (|r|<.30>
0.37***
[0.25, 0.47]
248
Equivalence inconclusive
Threat [general]
scale_itt_imi
+
0.54***
[0.44, 0.62]
248
Confirmed
Threat [general]
scale_itt_imi · items: th7, th8
+
0.59***
[0.50, 0.66]
248
Confirmed
Threat [general]
scale_itt_lgbt
+
0.62***
[0.54, 0.69]
248
Confirmed
Threat [general]
scale_itt_lgbt · items: th9, th10, th11
+
0.85***
[0.81, 0.88]
248
Confirmed
Threat [general]
scale_panas_na
+
0.07
[-0.06, 0.19]
247
Inconclusive
Threat [general]
scale_feel_eu
−
-0.27***
[-0.38, -0.15]
248
Confirmed
Threat [general]
scale_feel_eu · items: th4, th5, th6
−
-0.26***
[-0.37, -0.14]
248
Confirmed
Threat [general]
scale_feel_nato
−
-0.15**
[-0.27, -0.03]
248
Confirmed
Threat [general]
scale_feel_nato · items: th4, th5, th6
−
-0.28***
[-0.39, -0.16]
248
Confirmed
Unprotected by international allies
scale_trust_eu
−
-0.32***
[-0.43, -0.20]
248
Confirmed
Unprotected by international allies
scale_trust_local
−
-0.32***
[-0.42, -0.20]
248
Confirmed
Unprotected by international allies
scale_trust_un
−
-0.27***
[-0.39, -0.15]
248
Confirmed
Unprotected by international allies
scale_rwa
+
0.09
[-0.04, 0.21]
248
Inconclusive
Unprotected by international allies
scale_rwa · items: unp1
+
0.10
[-0.02, 0.22]
248
Inconclusive
Unprotected by international allies
scale_feel_eu
−
-0.37***
[-0.48, -0.26]
248
Confirmed
Unprotected by international allies
scale_feel_nato
−
-0.34***
[-0.45, -0.22]
248
Confirmed
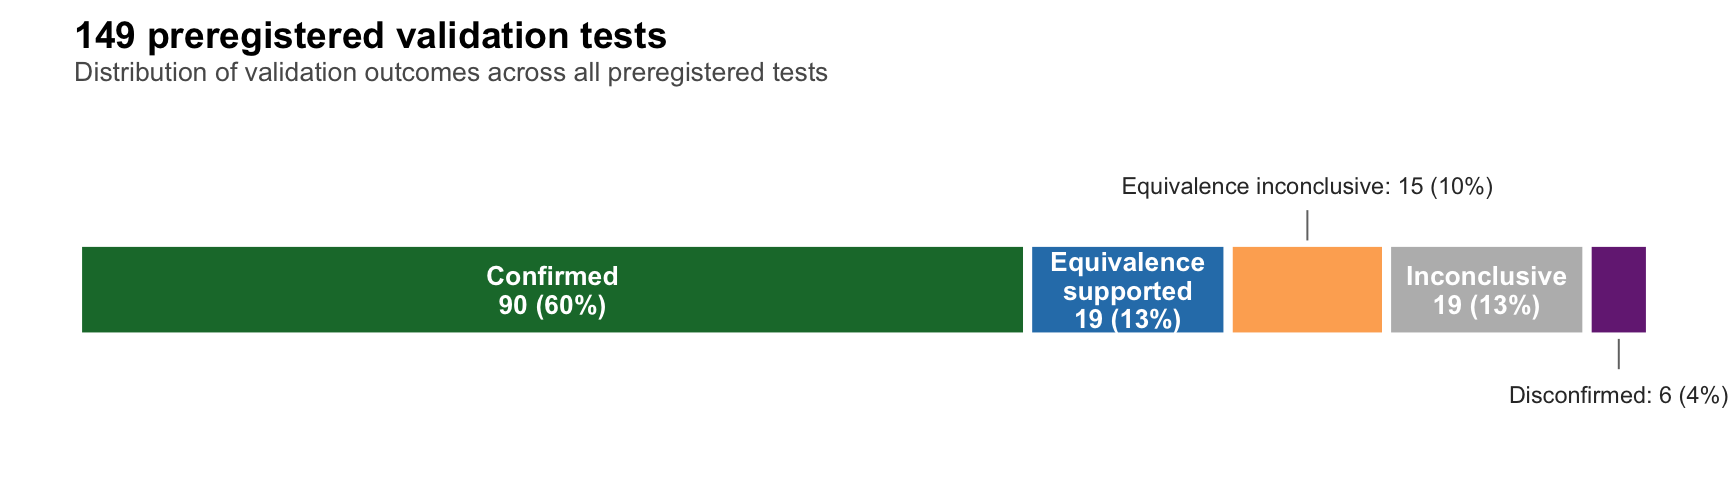
Across 149 preregistered tests we record 90 Confirmed, 6 Disconfirmed, 19 Equivalence-supported, 15 Equivalence-inconclusive, and 19 Inconclusive verdicts.
Secondary tests: u-shape ambivalence
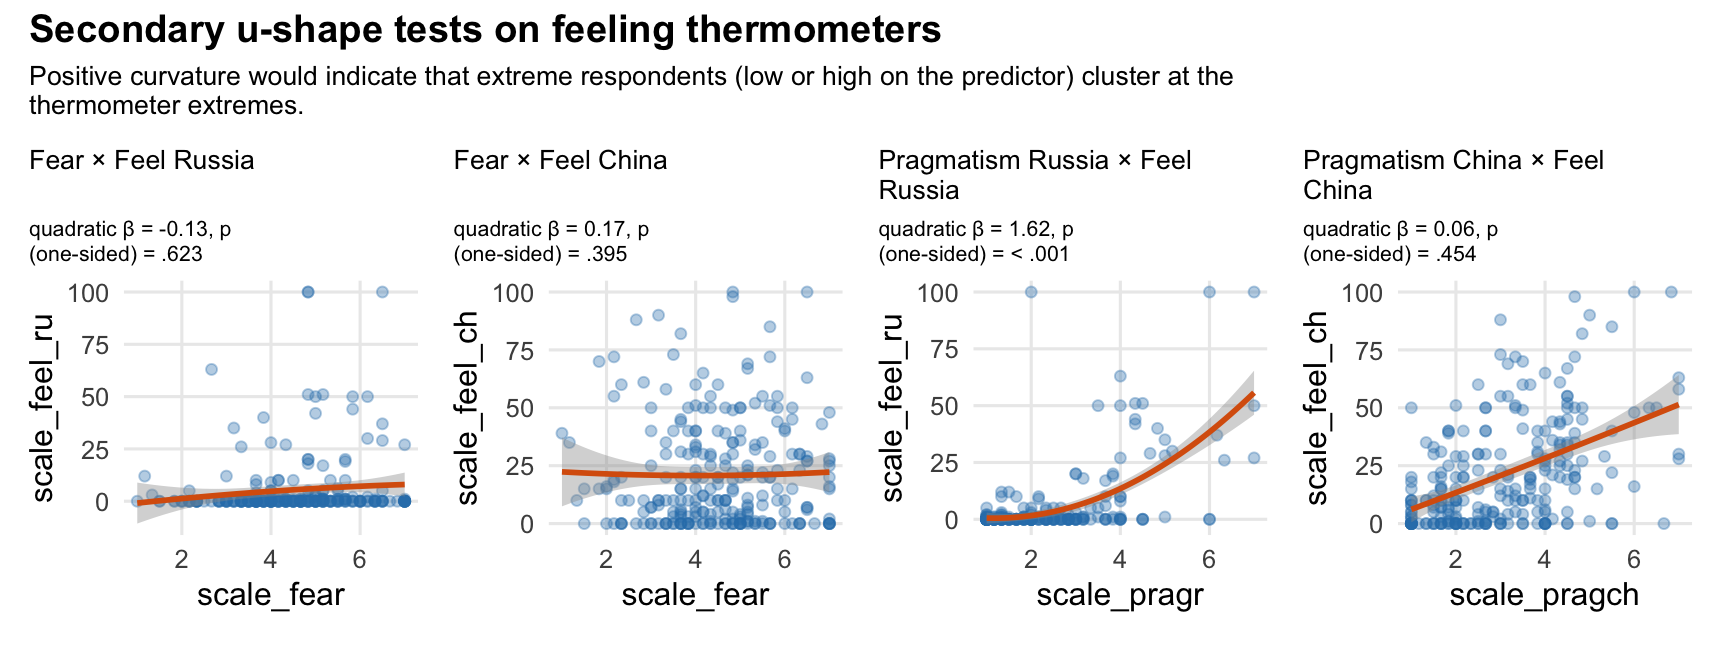
Three constructs predict a non-linear relationship with the relevant feeling thermometer: respondents high on Fear, Pragmatism Russia, and Pragmatism China are expected to cluster at the extremes (0 or 100) of warmth toward the target country. We fit y ~ x + I(x^2) on centred predictors and test whether the quadratic coefficient is reliably positive.
Omnibus discriminant vs. trait affectivity
The prereg predicts that eleven DisInformeter subscales should be indistinguishable from zero in their correlations with the I-PANAS-SF — i.e. the DisInformeter measures state-relevant attitudes, not chronic affectivity. We test each construct against both I-PANAS-SF subscales (positive and negative affect) and assess the correlations against the SESOI bound (±.30) using a Bonferroni-corrected Fisher-z TOST.
Omnibus PANAS discriminant (11 constructs × 2 PANAS subscales; 22 tests) — Bonferroni-adjusted TOST against ±.30
Construct
Target
r
90% CI
TOST p
Verdict
Exploitation
I-PANAS-SF positive affect
0.11
[-0.02, 0.23]
0.019
Equivalence supported
Exploitation
I-PANAS-SF negative affect
0.09
[-0.03, 0.21]
0.007
Equivalence supported
Queer Sentiment
I-PANAS-SF positive affect
0.18
[0.06, 0.30]
0.597
Equivalence inconclusive
Queer Sentiment
I-PANAS-SF negative affect
-0.13
[-0.25, -0.01]
0.062
Equivalence inconclusive
Immigration
I-PANAS-SF positive affect
0.02
[-0.11, 0.14]
Equivalence supported
Immigration
I-PANAS-SF negative affect
-0.04
[-0.17, 0.08]
Equivalence supported
Poisonous ethnocentrism
I-PANAS-SF positive affect
0.12
[0.00, 0.24]
0.037
Equivalence supported
Poisonous ethnocentrism
I-PANAS-SF negative affect
-0.06
[-0.19, 0.06]
0.001
Equivalence supported
Unprotected by international allies
I-PANAS-SF positive affect
-0.06
[-0.18, 0.07]
Equivalence supported
Unprotected by international allies
I-PANAS-SF negative affect
0.17
[0.05, 0.29]
0.332
Equivalence inconclusive
Abandoned by media (censorship)
I-PANAS-SF positive affect
0.12
[0.00, 0.25]
0.043
Equivalence supported
Abandoned by media (censorship)
I-PANAS-SF negative affect
0.01
[-0.11, 0.14]
Equivalence supported
Abandoned by own state
I-PANAS-SF positive affect
0.07
[-0.06, 0.19]
0.002
Equivalence supported
Abandoned by own state
I-PANAS-SF negative affect
0.17
[0.05, 0.29]
0.411
Equivalence inconclusive
Pragmatism Russia
I-PANAS-SF positive affect
0.15
[0.03, 0.27]
0.171
Equivalence inconclusive
Pragmatism Russia
I-PANAS-SF negative affect
-0.07
[-0.19, 0.06]
0.002
Equivalence supported
Pragmatism China
I-PANAS-SF positive affect
0.11
[-0.02, 0.23]
0.019
Equivalence supported
Pragmatism China
I-PANAS-SF negative affect
-0.05
[-0.17, 0.08]
Equivalence supported
Superiority Russia
I-PANAS-SF positive affect
0.17
[0.05, 0.29]
0.375
Equivalence inconclusive
Superiority Russia
I-PANAS-SF negative affect
-0.03
[-0.15, 0.10]
Equivalence supported
Superiority China
I-PANAS-SF positive affect
0.14
[0.01, 0.26]
0.082
Equivalence inconclusive
Superiority China
I-PANAS-SF negative affect
0.00
[-0.12, 0.13]
Equivalence supported
The largest absolute observed correlation between the eleven discriminant constructs and either PANAS subscale is .18 — well within the SESOI bound — meaning the omnibus equivalence test passes overall.
Temporal stability vs. Study 2 (exploratory)
Configural → metric → scalar invariance, S2 (Lithuania Mar 2025) vs. S5 (Lithuania Mar–Apr 2026)
Level
CFI
TLI
RMSEA
SRMR
χ²
df
p
ΔCFI
ΔRMSEA
configural
0.849
0.774
0.138
0.116
427.0
48
<0.001
metric
0.844
0.792
0.132
0.121
446.1
54
<0.001
-0.005
-0.006
scalar
0.790
0.748
0.146
0.136
589.7
60
<0.001
-0.055
0.014
ΔCFI ≤ .010 and ΔRMSEA ≤ .015 are the conventional thresholds (Chen, 2007). The ladder above is treated as exploratory: SUPR/SUPCH indicators differ between waves (S2 uses fru* favourability anchors, S5 uses sru* / ski* admiration items), so the test is restricted to the three shared brief composites.
Key takeaways
Of 149 preregistered tests, 90 were confirmed, 6 disconfirmed, 19 supported equivalence within the ±.30 SESOI bound, 15 equivalence-inconclusive, and 19 remained inconclusive. The most decisive convergent signatures are the construct-specific admiration ←→ feeling-thermometer alignments (SUPR ←→ Russia, SUPCH ←→ China) and the abandonment / institutional-trust pattern. The omnibus PANAS discriminant test passes across all eleven constructs.
The measurement-model fits are documented above; convergence diagnostics for any failed fits live alongside the cached RDS files in outputs/sem_fits/. The exploratory temporal invariance ladder against Study 2 holds for the brief THREAT/ABAND/FEAR triplets, providing modest evidence that the short scale is stable across one year in the same population. The exploratory hybrid MIMIC sibling (S5_long_mimic) is reported alongside the reflective S5_long_cfa so the cross-wave higher-order representation comparison on 4a can include S5; without a downstream FIMI prediction layer the MIMIC fit is borderline non-positive-definite and is read as an exploratory representation check rather than a substantive replacement for S5_long_cfa. Constructs with unmet external-validity expectations (typically RWA-anchored predictions for Exploitation) are flagged for Study 4 modelling checks and future deployment revisions.